Sɔʼ pəpúŋ“Welcome” in Ghomálá', a Bamiléké language of West Cameroon
Fokam Emeric
AI engineer and researcher, from models to production systems.
I build AI models, data pipelines and the backends that put them in production, with research in NLP and optimal transport on embedding spaces, and work on the languages of Cameroon.
AI engineer and researcher working across the full life cycle of AI systems, from theory to production. My core research is natural language processing through the lens of optimal transport: Wasserstein distances, spectral perturbation theory and eigenspace analysis to measure how multilingual embedding spaces move across models and source languages (Master's research, UMMISCO lab, IRD / University of Yaoundé 1).
Applied AI
On the applied side, I design LLM systems that reason and verify their answers: our few-shot text-to-SPARQL pipeline won the Spanish with-mentions track of the WikiKGQA challenge at ISWC 2026 and is published in CEUR-WS. I also take models to production for the languages and accents of Cameroon (Ghomálá' translation, Cameroonian-French speech recognition).
Backend engineering & integration
And I build the distributed backends that carry them: I maintained and evolved a real-time platform of 30+ event-driven microservices (RabbitMQ, Redis, Traefik) fed by sports odds providers, integrated Mobile Money payments and third-party APIs on NestJS SaaS products, and ship everything with Docker and CI/CD.
Research interests
Optimal transport
Wasserstein geometry
Spectral perturbation
Multilingual embeddings
Representation learning
Low-resource NLP
Speech recognition
Knowledge-graph QA
LLM reasoning & tool use
Event-driven microservices
Curious by nature, and open to neighbouring research questions.
Technical stack
Tools and methods
What I use, grouped by domain, and what I do with it.
Languages
Python
TypeScript
JavaScript
SQL
R
PHP
Machine learning
PyTorch
scikit-learn
TensorFlow
Hugging Face Transformers
NumPy
pandas
SciPy
Jupyter
LLMs & agentic AI
LangChain
LangGraph
LlamaIndex
CrewAI
Model Context Protocol
Hugging Face
Tool calling
Prompt engineering
Retrieval & vector search
RAG
FAISS
Chroma
pgvector
SPARQL
Data engineering
PostgreSQL
MariaDB
MySQL
Redis
RabbitMQ
Scrapy
Pentaho
ETL pipelines
Backend & integration
NestJS
Node.js
Django REST Framework
Flask
Next.js
Symfony
Prisma
OpenAPI
JWT / OAuth 2.0
Analytics & visualisation
Power BI
R Shiny
Plotly
Matplotlib
React dashboards
Gradio
Infrastructure
Docker
Traefik
GitHub Actions
Linux
Let's Encrypt
Hugging Face Spaces
Areas of work
From research to production
Each project sits in the domain it illustrates. Open a card for screenshots and technical details.
01
Machine Learning Engineering
Models are only useful once people can use them. I take them from the notebook to a running service.
Feature engineering, model selection and evaluation, deep learning with PyTorch and TensorFlow, model serving behind REST APIs. Neural machine translation, speech recognition and recommender systems taken to production.
PyTorch
◆Transformers
◆Seq2Seq
◆Wav2Vec 2.0
◆Recommender systems
◆Model serving
University of Yaoundé 1 × UMMISCO
Ghomala' Translate
Neural machine translation for an under-resourced language: French to Ghomálá', a tonal Bamiléké language of West Cameroon, backed by a sourced dictionary and an open contribution platform.
My core research is NLP through the lens of optimal transport: measuring how meaning moves between embedding spaces, models and languages.
Optimal transport for NLP: Wasserstein distances between embedding distributions, spectral perturbation theory and eigenspace analysis to quantify how multilingual representations shift across models and source languages. Applied side: LLM-based semantic parsing and knowledge-graph question answering over Wikidata.
Optimal transport
◆Wasserstein distance
◆NLP
◆Embedding geometry
◆Spectral perturbation
◆Multilingual representations
◆KGQA
Core research · Master's thesis, UMMISCO lab
WASER: optimal transport between embedding spaces
My main research line: how much does the meaning of a corpus move when it is embedded by different multilingual models or through different source languages? Optimal transport and spectral perturbation theory give a principled answer.
Benchmarks keep me honest: regular data science and AI competitions on Codabench, Kaggle and Zindi, and an active member of the KmerAI community.
KaggleZindiCodabenchNLP
03
Agentic AI & LLM Systems
I design LLM systems that reason, call tools and check their own answers instead of guessing.
Agent orchestration with LangChain, LangGraph and CrewAI, tool calling and Model Context Protocol servers, retrieval-augmented generation with LlamaIndex and vector stores (FAISS, Chroma, pgvector), multi-candidate sampling with execution-guided selection, open-weight model inference.
LangChain
◆LangGraph
◆LlamaIndex
◆CrewAI
◆MCP
◆RAG
◆Tool calling
ISWC 2026
Agentic pipeline for WikiKGQA
A generate–execute–select loop: the LLM writes candidate queries, runs them as a tool against the Wikidata endpoint and keeps the one that returns a valid answer.
A series of LLM application projects: chains, tool-using agents, state graphs and RAG pipelines.
LangChainLangGraphRAGVector stores
04
Data Engineering & Data Analysis
Reliable data comes first. I collect it, clean it, move it and turn it into decisions.
ETL pipelines, large-scale web scraping, relational data modelling, ingestion and runtime-data capture, message-based data flows and caching layers. Exploratory and statistical analysis, SQL analytics, interactive dashboards (Power BI, R Shiny, React) and decision-oriented reporting.
Web scraping
◆Scrapy
◆ETL
◆PostgreSQL
◆Orchestration
◆Dashboards
◆SQL
UMMISCO lab
Automated biblical text collection
Automated scraping system that builds corpora of biblical texts for the lab's natural language processing work.
Maintaining and extending a transactional platform of more than 30 microservices, fed in real time by odds and market providers (FeedConstruct, API-Sports).
Node.jsNext.jsRabbitMQRedis
Papers
Publications and research work
My core research on optimal transport for NLP, and a peer-reviewed paper on knowledge-graph question answering.
How much does a representation change when the same corpus is embedded with different multilingual models or source languages? This work models the geometric transformations of embedding spaces with spectral perturbation theory, and measures distances between representation distributions with Wasserstein optimal transport and eigenspace analysis.
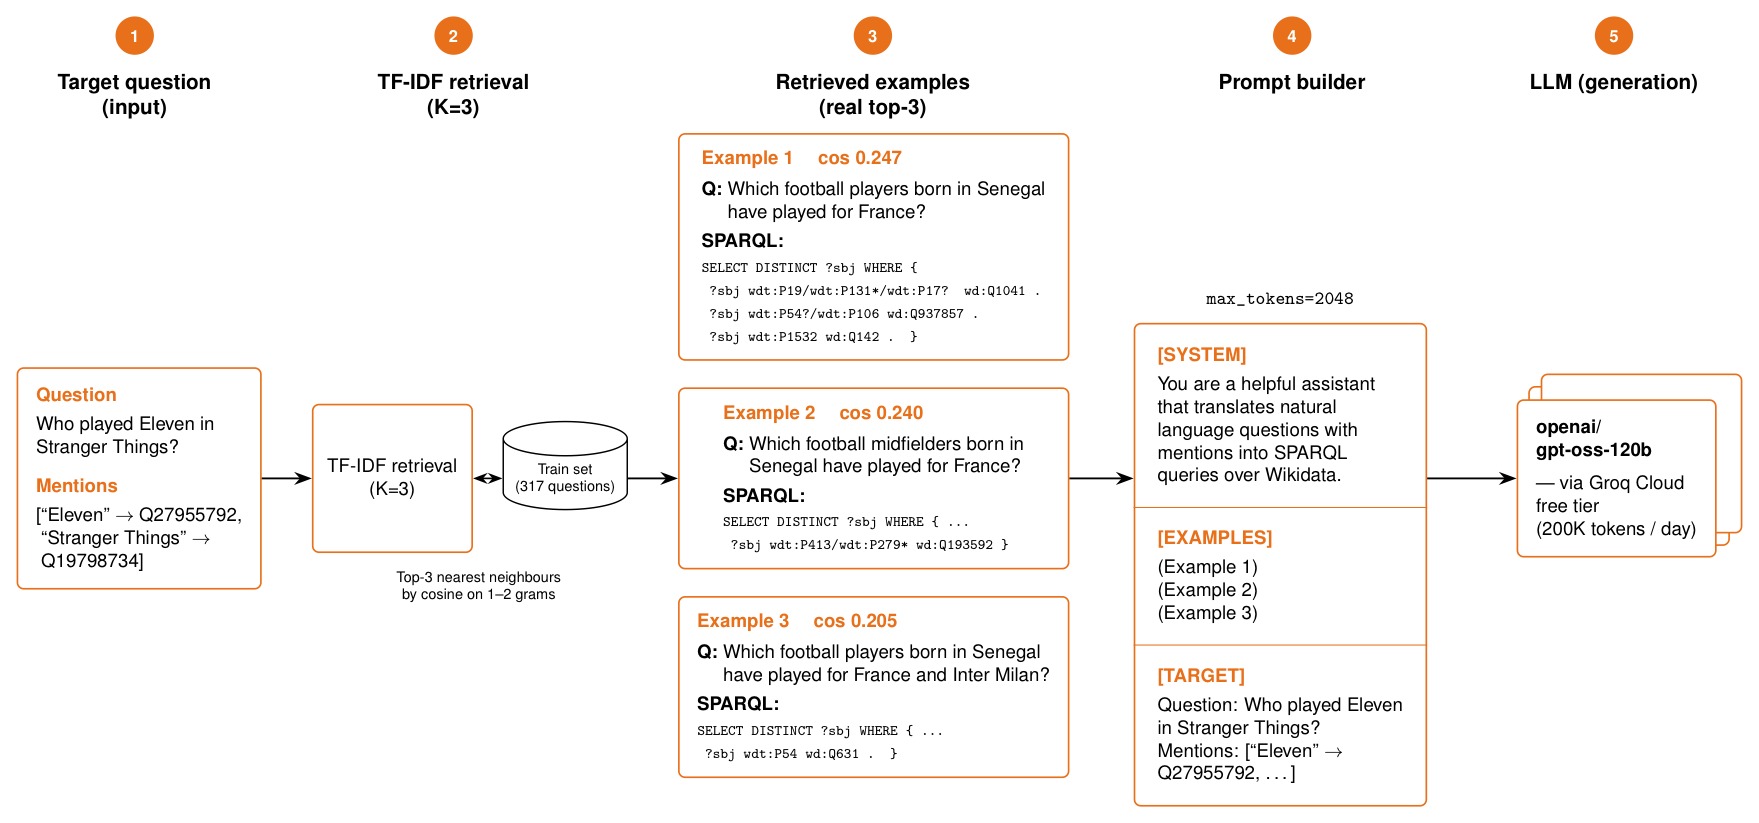
We report on our participation in the two with-mentions tracks (English and Spanish) of the WikiKGQA @ ISWC 2026 challenge, whose task is to translate a natural-language question into a SPARQL query executable against a Wikidata subgraph. Our system chains four stages: a TF-IDF retriever that selects three similar training examples, a few-shot prompt sent to an open-weight LLM, generation of five candidates with mixed temperatures (one deterministic, four at 0.7), and selection of the first candidate returning a non-empty result on the challenge endpoint. An error analysis isolates two resistant categories: type-filter questions, which rely on the P31/P279* chain that is incomplete on the endpoint, and COUNT queries, for which the LLM frequently forgets the aggregate. The pipeline uses only open-weight models (gpt-oss-120b, llama-3.3-70b) served free of charge through Groq Cloud.
Figure: processing of one question, from TF-IDF retrieval to LLM generation
Knowledge Graph Question AnsweringWikidataLarge Language ModelsSPARQL
My role: Paper presentation · WikiKGQA challenge track winner
ISWC is the premier international venue for research on the Semantic Web, knowledge graphs and linked data. The 2026 edition hosts the first WikiKGQA challenge, which evaluates question-answering systems over Wikidata in English and Spanish. I present our text-to-SPARQL system there, winner of the Spanish with-mentions track.
Benchmark: 492 bilingual English/Spanish question–SPARQL pairs built on QAWiki
Frozen Wikidata snapshot served by a dedicated QLever endpoint
Four tracks scored with macro QALD F1 on Codabench
Digital Avenues for Low-Resource Languages of Sub-Saharan Africa
DASSA'25
27–28 May 2025 Yaoundé, Cameroon (hybrid)
My role: Organising committee, logistics
International workshop of the African Society in Digital Sciences (ASDS), run by the AI4AfricanLanguages initiative with support from the French National Research Agency. It brings together researchers working on digital tools for under-resourced African languages. I was part of the organising team, in charge of logistics.
Topics: data collection and curation, speech recognition and synthesis, explainable ML, text–audio multimodality, annotation bias
Six accepted papers, from tone recognition to speech emotion recognition
Held at the CNS-RIC-DSU conference hall of MINESUP, Melen, Yaoundé
Mathematics and physical sciences: the foundations of everything that follows.
2020 – 2025
MSc in Computer Science, Data Science
University of Yaoundé 1 · Yaoundé
Five years of computer science, statistics and machine learning, completed with the DataCamp Data Scientist Professional track and four certifications.
2025
Master's thesis research
UMMISCO · Yaoundé
Into research: optimal transport and spectral perturbation theory to compare embedding spaces. In May, on the organising team of the DASSA'25 workshop on African low-resource languages.
Optimal transportNLPEmbeddings
Certifications
DataCamp · Data Scientist Professional
DataCamp · Data Analyst Professional
DataCamp · Data Scientist Associate
DataCamp · Data Analyst Associate
DataCamp · SQL Associate
Languages
FrenchNative
EnglishProfessional
Contact
Let's talk about your project
A need, a question or a collaboration: write to me, I reply within 24 hours.
 Python
 TypeScript
 JavaScript
 SQL
 R
 PHP
 PyTorch
 scikit-learn
 TensorFlow
 Hugging Face Transformers
 NumPy
 pandas
 SciPy
 Jupyter
 LangChain
 LangGraph
 LlamaIndex
 CrewAI
 Model Context Protocol
 MariaDB
 MySQL
 Redis
 RabbitMQ
 Scrapy
 NestJS
 Node.js
 Django REST Framework
 Flask
 Next.js
 Symfony
 Prisma
 OpenAPI
 JWT / OAuth 2.0
 Plotly
 React dashboards
 Gradio
 Docker
 Traefik
 GitHub Actions
 Linux
 Let's Encrypt